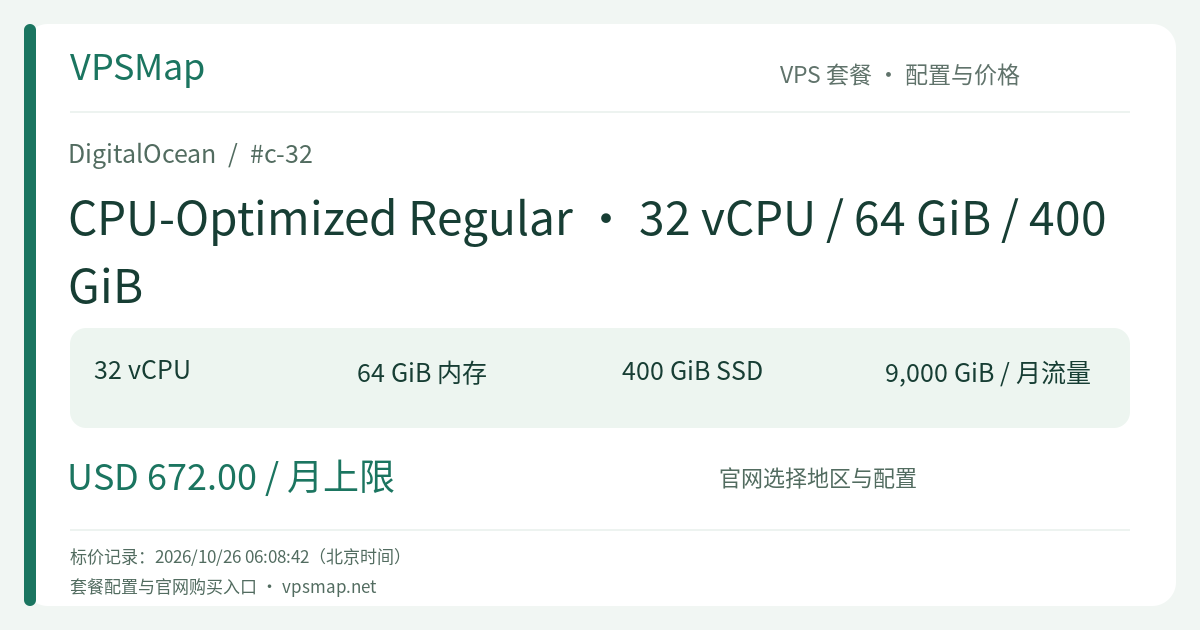
DigitalOcean c-32 In-Depth Review: High-Efficiency Dedicated 32 vCPU Workhorse for Builds & Batch Compute
Updated
Why Dedicated Compute Is the Turning Point for Heavy Workloads#
When your codebase spans hundreds of thousands of lines, your CI/CD pipeline queues stretch beyond 30 minutes, or your video transcoding queue begins falling behind, shared-CPU virtual machines inevitably introduce destructive unpredictability. Under shared CPU architectures, noisy neighbors can claim hypervisor cycles without warning, turning a 15-minute integration run into a 45-minute slog or a failed timeout.
DigitalOcean c-32 eliminates this performance lottery:
- Guaranteed Hyper-Thread Allocation: All 32 vCPUs are pinned to dedicated physical hyper-threads. You get 100% of your allocated processing capacity at all times, with base clock speeds remaining rock-solid above 2.6 GHz and zero CPU steal.
- Optimized 1:2 RAM-to-CPU Ratio: Armed with 64 GiB of RAM, this plan is engineered specifically for compute-bound tasks. Engineering teams often end up overpaying for General Purpose or Memory-Optimized instances with hundreds of unused gigabytes of RAM just to obtain 32 cores. The c-32 keeps resource overhead lean and maximizes your compute ROI.
- 400 GiB Directly Attached Local SSD: Provides immediate, low-latency disk storage for local workspaces, multiple active Docker base layers, and rapid build output staging.
Where c-32 Truly Excels#
1. Self-Hosted Enterprise CI/CD Runners (GitLab CI & GitHub Actions)#
If your organization has hit rate limits or concurrency ceilings on shared SaaS runners, deploying a self-hosted runner node on a c-32 delivers an instant productivity boost. Thirty-two dedicated threads easily support parallel test matrices, heavy multi-target compilation in C++, Rust, or Go, and dozens of isolated concurrent test containers.
2. High-Throughput Video Transcoding (FFmpeg Pipelines)#
Video slicing, audio re-encoding, and CPU-driven H.264/H.265/AV1 exports demand unyielding CPU cycles. Without the prohibitive costs of dedicated GPUs, c-32 provides massive parallel core density to process multiple simultaneous 1080p and 4K streams smoothly for media platforms, EdTech portals, and streaming origins.
3. Distributed Batch Workers & High-Concurrency Reverse Proxies#
Whether you are handling peak-hour dynamic Brotli/Gzip compression, bulk SSL termination, or scheduled offline batch jobs and data cleaning scripts, c-32 absorbs massive concurrency spikes without jitter in your API response latencies.
Storage and Networking Synergies#
- Local Disk Strategy: The 400 GiB included local SSD is optimized for the operating system, container runtime layers, and active scratch data. For permanent persistent storage, seamlessly attach DigitalOcean Volumes (Block Storage) or offload immutable artifacts directly to Spaces Object Storage.
- 9,000 GiB Pooled Outbound Transfer: The c-32 includes 9,000 GiB of free monthly outbound bandwidth, while inbound transfer is always free. Furthermore, DigitalOcean pools bandwidth at the team level across all your Droplets. Spikes on one active instance are cushioned by idle instances across your fleet, with predictable overages billed at only $0.01 per GiB.
- Free Private VPC Networking: Droplets communicating within the same regional VPC transmit data securely over private network interfaces with zero bandwidth charges and ultra-low latency, ideal for orchestrating internal microservices and worker queues.
Flexible Billing: Sustained Reliability or Ephemeral Crunching#
DigitalOcean combines per-second billing with a transparent monthly cap (pegged at 672 hours, or 28 days):
- 24/7 Production Nodes: Even when operating non-stop across a 31-day calendar month, your charges halt at the 672-hour ceiling, keeping your monthly spend predictable.
- On-Demand Ephemeral Jobs: Need 32 cores for just a 4-hour full integration run on release day? Spin up a c-32 via doctl or the API, complete the workload, and destroy it immediately. You pay strictly for the exact runtime down to the second, turning enterprise-tier parallel compute into an agile, low-cost utility.
Note: Powering off a Droplet in the control panel keeps its hypervisor compute resources reserved for you, which means billing continues. To stop charges completely, destroy the Droplet.
Decision & Sizing Matrix#
- Choose c-32 if 400 GiB of local scratch storage satisfies your operating system and caching requirements.
- Step up to
c2-32vcpu-64gb(800 GiB) orc5-32vcpu-64gb(2000 GiB) if your pipelines store heavy local datasets or massive Docker image registries and you want to bypass the complexity of external storage volumes. - Move to General Purpose only if your application's memory footprint consistently requires a 4:1 RAM-to-vCPU ratio.
To provision your dedicated 32-core node and verify regional data center availability, access the deployment portal directly: Deploy your DigitalOcean c-32 Droplet.