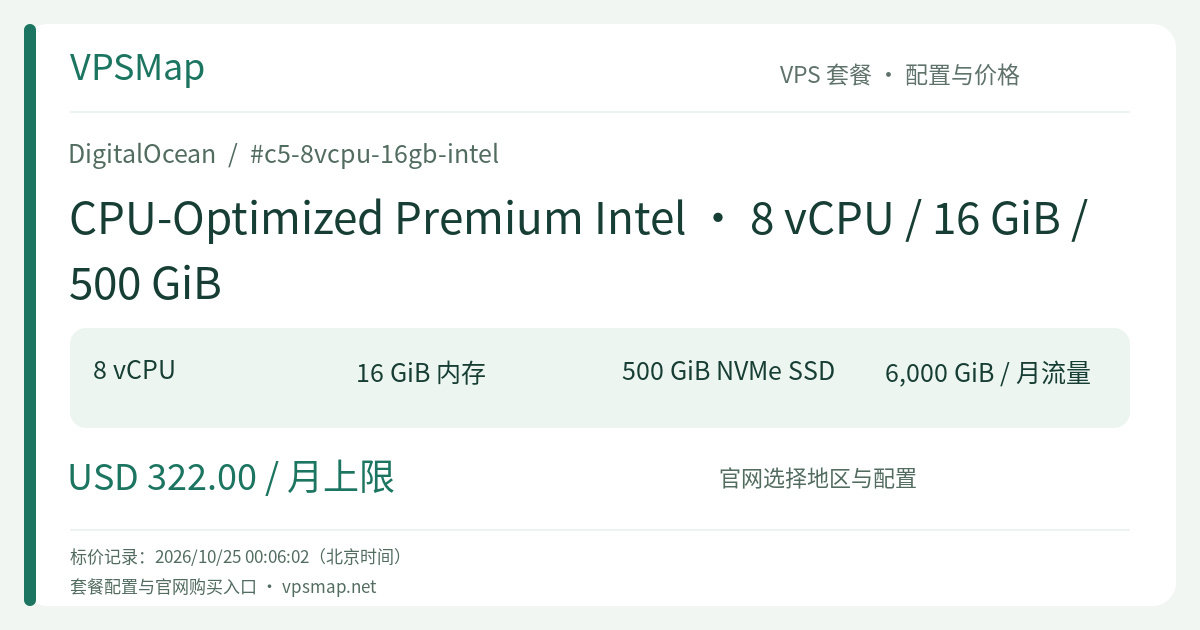
DigitalOcean c5-8vcpu-16gb-intel Deep Dive: 500 GiB Local NVMe & 8 Dedicated Cores for Extreme Transcoding & Data Workloads
Updated
The Raw Advantage of 500 GiB Local NVMe: Eradicating the I/O Bottleneck#
In high-performance computing, the "bottleneck effect" is merciless: even if you unleash 8 blazing-fast CPU cores, any latency in underlying disk reads and writes immediately causes your processing threads to fall into idle I/O Wait states.
When dealing with extreme, data-heavy workflows—such as automated 4K/8K video transcoding, continuous decompression and repackaging of multi-gigabyte archives, indexing millions of files, or compiling sprawling mono-repos—traditional cloud instances bottlenecked by network-attached block storage cannot feed the CPU fast enough.
The c5-8vcpu-8gb-intel Droplet (8 vCPU / 16 GiB / 500 GiB NVMe) was engineered to break this exact bottleneck. It pairs 8 dedicated Intel Ice Lake hyper-threads and 16 GiB of RAM with an enormous 500 GiB direct-attached local NVMe SSD. Half a terabyte of raw local flash storage communicates directly over the physical PCIe bus at multi-gigabyte-per-second throughput, with zero network virtualization overhead.
8 Dedicated Intel Ice Lake Threads Running at Sustained Full Throttle#
Complementing its massive local disk is a dedicated, enterprise-grade compute foundation:
- Isolated Compute Power: Powered by 3rd Generation Intel Xeon Scalable processors (Ice Lake) with stable base clock speeds above 2.6 GHz. All 8 hyper-threads are dedicated to your Droplet. Whether running flat-out for two hours or two weeks, your compute capacity never wavers.
- AVX-512 Hardware Vector Acceleration: Built-in support for advanced vector instruction sets. Mathematical modeling, heavy cryptographic hashing, and modern video encoding codecs (H.265/HEVC, AV1, ProRes) achieve dramatic speedups.
- 10 Gbps High-Throughput Network Interface: Premium Intel instances unlock a 10 Gbps networking pipeline. Ingesting dozens of gigabytes of raw footage or training datasets from Spaces object storage takes minutes, eliminating transit delays across your processing chain.
The Triple Synergy: Compute, Storage, and 10 Gbps Networking#
This configuration represents an optimal closed-loop architecture for heavy batch operations:
- High-Speed Network Ingestion: The 10 Gbps interface ingests massive raw data feeds from remote sources at hundreds of megabytes per second.
- Zero-Latency Local Staging: 500 GiB of native NVMe absorbs high-volume sequential and random writes, ensuring uncompressed frame buffers and build caches never stall.
- 8 Dedicated Cores at Full Saturation: With zero I/O wait, all 8 dedicated cores run at 100% capacity on transcoding, compilation, or transformation logic.
- Seamless Distribution via Pooled Bandwidth: Finished outputs stream quickly to end-users via the 6,000 GiB team transfer pool or securely over private VPC links to persistent storage.
Target High-Intensity Workloads#
- 4K / 8K High-Definition Transcoding and Streaming Packaging: Ingesting high-bitrate video masters, generating intermediate frame caches, and rendering multi-bitrate HLS/DASH streaming profiles. A 500 GiB NVMe drive holds numerous raw video masters simultaneously, keeping all 8 cores continuously fed.
- Massive Mono-Repo Compilation and Game Engine Builds: Compiling complex multi-component codebases like game engines, AOSP Android source, or custom kernel distributions. Multi-gigabyte compilation caches (ccache, sccache) can be pinned locally on the NVMe disk for dramatic build acceleration.
- Heavy Offline Data Cleaning, Tokenization, and ETL: Processing billions of log events or hundreds of thousands of images prior to database ingestion or ML model training. The 500 GiB drive acts as an ultra-fast local shuffle space for intensive file I/O.
Maximizing ROI: Precision Per-Second Billing#
While a top-tier configuration may seem like a major commitment, a smart operational design makes it remarkably cost-effective:
- Spin Up On-Demand, Destroy When Done: The c5-8vcpu-16gb-intel Droplet is billed per second (60-second minimum or $0.01). If your business requires a nightly 3-hour transcoding batch run, automate droplet provisioning via the DigitalOcean API, execute the workload, upload results to Spaces, and immediately destroy the server. You pay only for the exact runtime.
- Predictable Cap for Continuous Operations: When utilized as a permanent dedicated build engine, monthly usage caps at 672 hours (28 days). Any additional hours in that month are completely free of compute charges.
- Compute Reservation Rule: Because all 8 physical hyper-threads and 500 GiB of local NVMe storage are reserved on the physical hardware, a "Powered Off" Droplet continues to incur charges. Always destroy temporary worker nodes when jobs complete.
Sizing Verdict & Deployment#
When your operational pipeline pushes both multi-threaded CPU performance and hundreds of gigabytes of raw disk I/O throughput to the absolute edge, compromising on hardware costs you time and reliability. The DigitalOcean c5-8vcpu-16gb-intel is an unapologetic, top-tier performance workhorse.
Datacenter capacity is verified live inside the control panel during deployment. Spin up your instance directly via the link below:
Deploy the c5-8vcpu-16gb-intel 8-Core Droplet on DigitalOcean