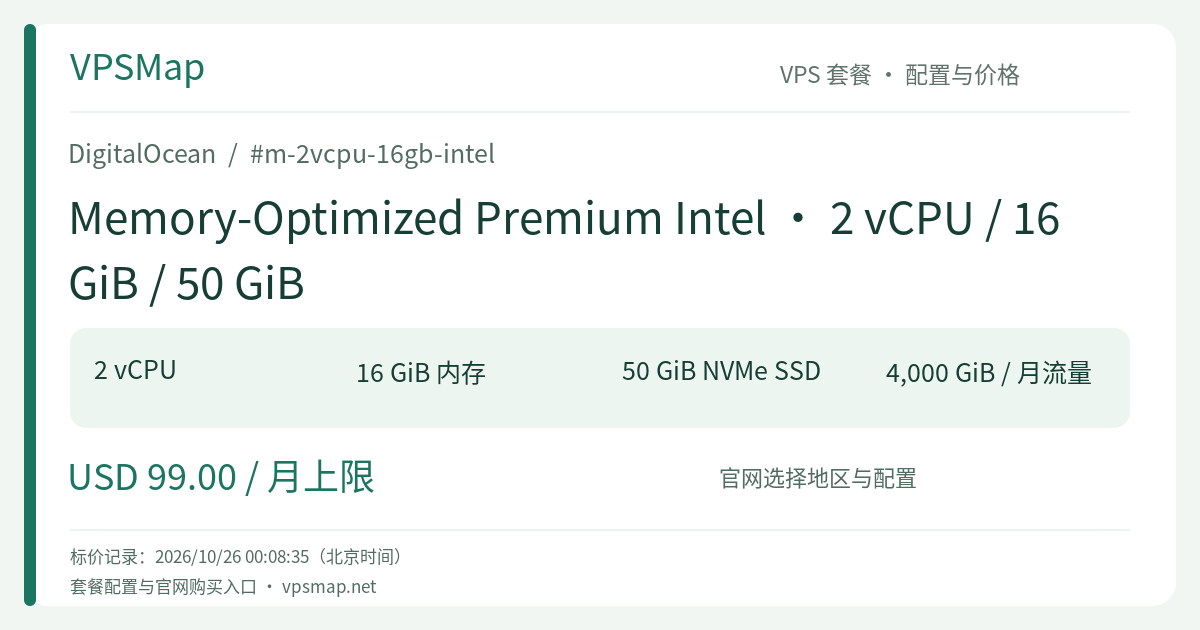
DigitalOcean Memory-Optimized 2 vCPU / 16 GiB (Premium Intel) Review: Dedicated In-Memory Power Without OOM Crashes
Updated
The Architectural Case for a 1:8 Compute-to-Memory Ratio#
In standard cloud server configurations, general-purpose instances usually adopt a 1:2 or 1:4 vCPU-to-RAM ratio (such as 2 vCPU / 4 GiB or 2 vCPU / 8 GiB). However, modern production architectures frequently encounter workloads where raw compute requirements are modest, but memory footprint is immense.
Classic real-world examples include:
- Standalone Redis / KeyDB In-Memory Caching Layers: Millions of keys must live directly in RAM. While two dedicated cores easily serve hundreds of thousands of QPS, 8 GiB of memory quickly causes eviction alerts and fragmentation.
- PostgreSQL / MySQL Read Replicas: The query processing load may be light, but generous Linux Page Cache is vital to keep entire indexes warm in memory and prevent blocking disk I/O.
- Multi-Process Background Workers: Platforms running Python Celery, Ruby Sidekiq, or PHP-FPM pools allocate fixed memory per process. Under sudden queue surges, general-purpose servers often sit at 30% CPU utilization while RAM is completely exhausted, prompting the Linux OOM-Killer to terminate critical daemons.
DigitalOcean's Memory-Optimized 2 vCPU / 16 GiB (Premium Intel) Droplet is engineered to solve this mismatch. Pairing 2 dedicated execution threads with 16 GiB of reliable physical RAM ensures operational stability without forcing you onto expensive 4-core or 8-core instances.
Hardware Advantages: The Premium Intel Difference#
This Droplet is powered by 3rd Generation Intel Xeon Scalable processors (Ice Lake) designed for enterprise predictability:
- 100% Dedicated vCPUs Unlike shared Basic Droplets that compete for hypervisor cycles, dedicated vCPUs are pinned to real physical hyper-threads. Your workloads remain unaffected by neighboring tenants, completely eliminating noisy-neighbor latency spikes.
- 2933 MHz Memory Frequency For in-memory datastores and Java/Node.js runtimes, memory latency directly governs P99 response times. Premium Intel instances feature optimized memory bus architectures, delivering stable microsecond lookups under heavy concurrency.
- Directly-Attached NVMe Boot Storage (50 GiB) Local NVMe solid-state storage connects directly to the hypervisor bus, ensuring rapid operating system boot times, instantaneous package operations, and low-latency WAL/AOF write flushes compared to standard SATA SSDs.
- 10 Gbps Network Pipe Premium configurations feature up to 10 Gbps of network throughput—up to five times faster than standard instances. Whether streaming replication streams to database replicas or fetching bulk datasets from object storage, networking will never be your bottleneck.
Storage Positioning & Workload Trade-offs#
With 50 GiB of local NVMe storage, this Droplet is built with clear architectural intent:
- Best suited for: Pure in-memory caching (Redis, Memcached), stateless microservices, queue orchestrators, and database read replicas where persistent storage is either modest or offloaded.
- Considerations: After OS installation and log allocations, usable disk space stands around 35–40 GiB. If your application requires hundreds of gigabytes of on-disk transactional history or heavy raw files, choose the
m3series (which provides 150 GiB of local NVMe for a minor incremental cost) or attach a DigitalOcean Volumes block storage drive.
Predictable Billing & Bandwidth Pooling#
- Per-Second Billing with Monthly Cap: Charged per second with a 672-hour (28-day) monthly cap. Even in a 31-day month, your bill will never exceed the 672-hour ceiling for continuous usage.
- Power-Off Retention Policy: Because 2 dedicated Xeon cores and 16 GiB of physical memory remain reserved on the hypervisor, stopping the Droplet inside the OS or via the console still accrues charges. To stop billing permanently, take a snapshot and destroy the instance.
- 4,000 GiB Team Bandwidth Pool: Comes with 4,000 GiB of included outbound transfer, while inbound traffic is completely free. Bandwidth is pooled cumulatively across all Droplets on your team, and excess outbound bandwidth is billed at a flat $0.01 per GiB.
Practical Production Optimization#
To maximize the performance of your 16 GiB memory footprint, apply these production kernel parameters:
# Minimize kernel swapping aggression to prioritize physical RAM
sysctl vm.swappiness=1

# Ensure Redis background saves (BGSAVE) fork safely without memory exhaustion errors
sysctl vm.overcommit_memory=1

# Expand TCP connection backlog for high-volume socket traffic
sysctl -w net.core.somaxconn=1024
Deploy your dedicated memory-optimized server via the official console:
👉 Deploy the 2 vCPU / 16 GiB Premium Intel Droplet on DigitalOcean