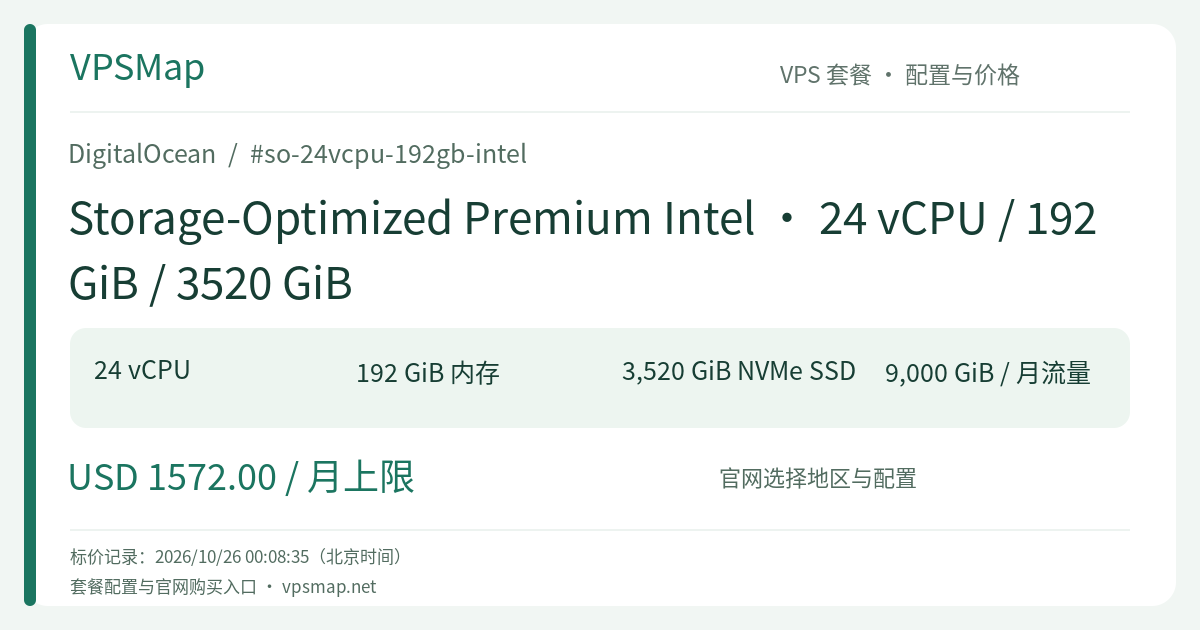
DigitalOcean 24 vCPU / 192 GiB Storage-Optimized Premium Intel: The Enterprise Foundation for Heavy Ingestion and Big Data Search
Updated
The Concurrency Threshold: When 16 Cores Are Stretched#
As growing systems transition into mature enterprise production workloads, infrastructure teams often encounter a distinct architectural bottleneck: sustained, non-stop concurrent resource contention.
On 16-core servers under heavy production load, symptoms manifest predictably:
- While processing thousands of concurrent user queries, background tasks—such as PostgreSQL auto-vacuuming, MySQL index reorganizations, or scheduled analytics—push CPU utilization above 90%.
- Bulk ingest requests in search clusters begin competing with client search queries for CPU threads, causing search latency to spike.
- After allocating 31 GiB of JVM heap and operational memory on a 128 GiB node, available headroom for the operating system's filesystem page cache starts running thin.
The so-24vcpu-192gb-intel (Storage-Optimized 24 vCPU / 192 GiB) Droplet addresses this scaling point directly. By expanding compute, memory, and direct NVMe capacity in lockstep, it delivers the stability required for critical enterprise tiers.
Tri-Fold Hardware Synergies: 24 Cores / 192 GiB / 3.5 TB NVMe#
This instance provides a balanced configuration engineered for high-throughput transactional and analytical applications:
1. 24 Dedicated Premium Intel Xeon Cores#
Upgrading from 16 to 24 dedicated cores represents a 50% increase in dedicated compute capacity. Complex multi-table analytical joins, window functions, and Lucene inversion index pipelines benefit from uninterrupted execution threads, shielding foreground customer transactions from background workload interference.
2. 192 GiB Enterprise Memory Pool (8:1 Ratio)#
The 192 GiB memory footprint provides substantial operational headroom:
- Search Clusters: With JVM heap capped at 31 GiB, over 150 GiB of RAM remains dedicated to the Linux kernel page cache. Terabytes of frequently accessed index segments remain cached in physical memory, transforming slow disk reads into microsecond RAM fetches.
- Relational Databases: An expansive InnoDB Buffer Pool or PostgreSQL shared memory pool (140+ GiB) keeps database hit ratios above 99%.
3. 3520 GiB Direct-Attached NVMe Flash#
3.5 TB of hypervisor-attached NVMe storage supports continuous multi-client write concurrency. Direct PCIe bus routing ensures that write-ahead logs (WAL) commit instantaneously without network queuing.
4. 10 Gbps Networking with 9000 GiB Transfer Pool#
The public bandwidth allowance expands to 9000 GiB monthly, coupled with a 10 Gbps port speed. Snapshot generation, read-replica replication, and external API traffic operate without networking bottlenecks.
Production Architecture & Target Scenarios#
[10 Gbps Ingress / Application Layer]
              │
              ▼
┌──────────────────────────────────────────────┐
│         so-24vcpu-192gb-intel Node           │
│  ├── 24 Dedicated Xeon Cores: Parallelism    │
│  ├── 192 GiB RAM: 150G+ OS Cache Capacity    │
│  └── 3520 GiB Direct NVMe: PCIe Low-Latency  │
└──────────────────────────────────────────────┘
              │
   [Free VPC Private Network (Replication)]
              ▼
┌──────────────────────────────────────────────┐
│       Read Replicas / Downstream Nodes       │
└──────────────────────────────────────────────┘- Core Transactional Systems for SaaS & E-Commerce: Seamlessly handle flash promotions and peak checkout volumes without database connection timeouts.
- Centralized Logging and SIEM Platforms: Serve as the core indexing and search engine for high-volume OpenSearch or Elasticsearch clusters.
- Real-Time Stream Processing State Backends: Act as high-throughput state storage (e.g., Apache Flink with RocksDB state backend on local NVMe), maintaining checkpointing speeds under continuous high-volume streaming.
Procurement and Value Assessment#
Priced at $1,572.00/month ($2.33929/hour), this plan follows DigitalOcean's transparent 672-hour monthly billing cap.
When evaluating this investment against total cost of ownership (TCO):
- Consolidating complex data tiers onto a single 24-core / 192 GiB high-performance node eliminates distributed locking overhead, cross-node network latency, and the ongoing operational maintenance associated with multi-node clusters.
- Ample compute and memory headroom keeps daily operational utilization within a healthy 50%–70% window, preventing emergency performance firefighting during unexpected traffic spikes.
[!NOTE] Operational Note: Direct-attached hardware remains reserved on the host machine while the Droplet exists. Billing continues during powered-off states until the Droplet is destroyed. Use VPC private networking for zero-cost replication across your infrastructure.