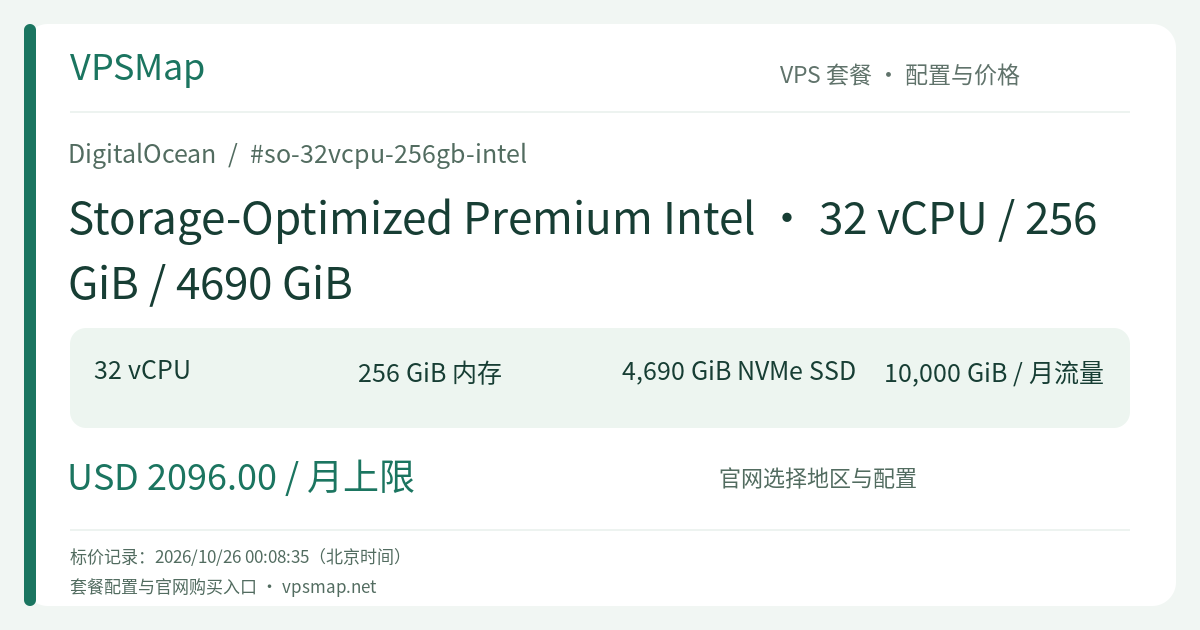
DigitalOcean 32 vCPU / 256 GiB Storage-Optimized Premium Intel: The Monolithic Powerhouse for High-Concurrency Core Databases
Updated
The Elegance of Vertical Scale: Why Big Monoliths Often Win#
In modern engineering, the default reaction to scaling challenges is often to split applications into distributed micro-nodes. While distributed architectures have their place, premature distribution frequently introduces severe engineering friction:
- Distributed Transaction Overhead: Two-phase commits (2PC), cross-shard locking, and network communication latency can degrade response times on operations that are trivial on a single server.
- Operational Complexity: Doubling or tripling node counts multiplies monitoring noise, split-brain scenarios, backup orchestration overhead, and cluster rebalancing complexity.
- Network Contention: Continuous data movement between nodes consumes infrastructure bandwidth and creates latency bottlenecks.
For many organizations, the most effective architectural choice is a powerful, vertically scaled primary node. The DigitalOcean so-32vcpu-256gb-intel (Storage-Optimized 32 vCPU / 256 GiB / 4690 GiB NVMe) is designed to handle this core tier reliably.
Flagship Hardware Breakdown: 32 Cores / 256 GiB / 4.7 TB NVMe#
This configuration pushes compute, memory, and local I/O capacity to top-tier enterprise standards:
1. 32 Dedicated Premium Intel Xeon Cores#
Powered by 3rd Generation Intel Xeon Scalable processors, 32 dedicated cores provide massive concurrent execution capacity. Complex analytical aggregation, heavy database write bursts, or hundreds of parallel background threads run without CPU throttling or thread contention.
2. 256 GiB Enterprise Memory Pool#
A quarter-terabyte of memory simplifies application tier architecture:
- Relational Databases (PostgreSQL / MySQL): Allocate 180+ GiB to buffer pools, keeping multi-million-row working sets and active indexes cached in RAM to reduce physical disk reads to near zero.
- Search Clusters (Elasticsearch / OpenSearch): Cap the JVM heap at 31 GiB to maintain efficient pointer compression, leaving over 220 GiB of RAM dedicated to the Linux kernel page cache. Lucene index files across the entire 4.6TB disk array operate with near-instantaneous memory-mapped access.
3. 4690 GiB Direct-Attached NVMe Flash#
With 4.6TB of NVMe flash connected directly to the physical PCIe bus, write-ahead logging (WAL) and write-heavy workloads execute at native hardware speeds. Direct hypervisor attachment avoids virtual network encapsulation delays.
4. 10 Gbps Network Pipe & 10,000 GiB Transfer Pool#
A 10 Gbps virtual interface paired with a 10,000 GiB monthly transfer pool (free inbound) guarantees that high-traffic public API egress and background data replication operate without network interface saturation.
Target Workload Scenarios#
| Domain | Role | Key Architectural Benefit |
|---|---|---|
| Core Enterprise OLTP Primary | Primary Transaction Database | 32 dedicated cores eliminate connection bottlenecks; 256GB RAM caches critical tables; 4.6TB NVMe provides fast write response |
| ClickHouse / StarRocks Real-Time Analytics | Analytical Compute Node | 32 parallel execution threads query billions of records; direct NVMe delivers high multi-channel read throughput |
| Enterprise Log & APM Search Engine | Core Search & Indexing Node | Over 220 GiB of OS page cache accelerates Lucene queries; 4.6TB local flash keeps historical logs immediately accessible |
| Large Monorepo CI/CD Build Server | Dedicated Build Master | 32 cores handle parallel compilation pipelines; massive memory caches build dependencies efficiently |
Cost and Architectural Value ($2,096/mo)#
Listed at $2,096.00/month ($3.11905/hour), this instance serves mission-critical environments where application availability and throughput directly drive revenue.
DigitalOcean maintains a predictable pricing structure:
- 672-Hour Monthly Cap: You are billed per second up to 672 hours (28 days) per month. Any additional hours in a calendar month are free.
- All-Inclusive Performance: All IOPS and bandwidth from the 4.6TB direct-attached NVMe drive are fully accessible without provisioned IOPS surcharges or hidden throughput fees.
[!IMPORTANT] High Availability Best Practices: Direct-attached NVMe provides top-tier performance by residing on the physical hypervisor. In production environments, never run a single point of failure without an automated replica. Pair this node with an active standby replica over the free private VPC network to ensure seamless failover.