DigitalOcean c-32-intel Droplet Guide: 32 Dedicated Cores for Enterprise Workloads
Updated
The Case for 32 Dedicated Cores in Production#
As applications scale, microservice clusters, CI/CD matrices, and API gateways face exponential growth in traffic and computational demand. Horizontally stacking smaller instances can introduce connection pool saturation, cross-node network latency, and operational overhead. At the same time, vertically scaling on shared-CPU hardware introduces the risk of noisy-neighbor slowdowns.
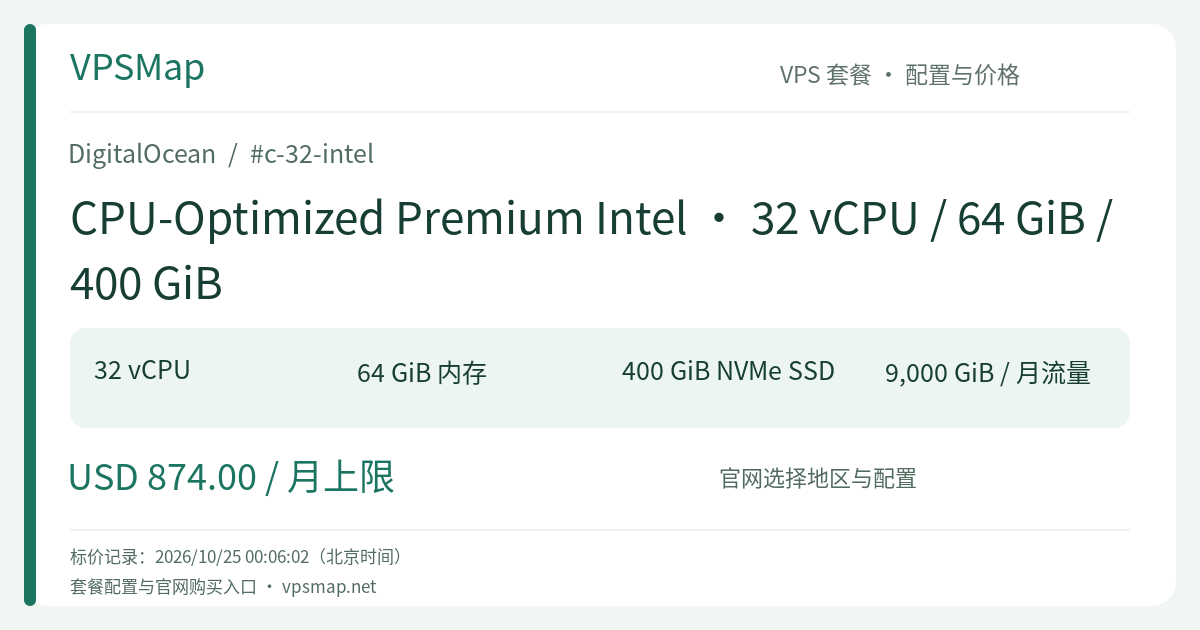
The DigitalOcean c-32-intel Droplet belongs to the CPU-Optimized Premium Intel tier. It delivers 32 dedicated hyper-threads powered by 3rd Gen Intel Xeon Scalable processors (base clock > 2.6 GHz), paired with 64 GiB of RAM and 400 GiB of local NVMe storage. This instance is engineered for demanding workloads requiring predictable, deterministic throughput.
Architectural Strengths & Technical Highlights#
1. 32 Dedicated Xeon Cores: Absolute Predictability#
In mission-critical environments, inconsistent latency is as damaging as outright downtime. The c-32-intel assigns 32 dedicated physical hyper-threads exclusively to your virtual machine. Unaffected by neighboring host activity, your build matrices, live stream transcoders, and microservices maintain uninterrupted, full-speed execution.
2. The 2:1 Compute-to-Memory Ratio (64 GiB RAM)#
While general-purpose instances often bundle 128 GiB of RAM with 32 cores, c-32-intel leverages an optimized 2:1 ratio:
- Generous 64 GiB Memory: Ample headroom to run high-concurrency Go, Rust, or Node.js workers and handle compilation spikes without memory exhaustion.
- Cost Efficiency: You avoid paying a premium for unneeded RAM, lowering the total cost per dedicated compute unit for CPU-bound tasks.
3. 10 Gbps High-Throughput Network & 9,000 GiB Bandwidth Pool#
Premium Intel Droplets include high-bandwidth network interfaces capable of delivering up to 10 Gbps of outbound throughput—up to 5x faster than standard regular-CPU Droplets. With 9,000 GiB of included monthly public transfer pooled across your team (inbound is free), your server can easily distribute large media files, sync container images, and process high-volume API requests.
4. Hypervisor-Attached 400 GiB NVMe Disk#
The 400 GiB NVMe SSD is wired directly to the hypervisor bus, delivering superior IOPS and sub-millisecond latencies compared to network-attached block volumes. This accelerates local scratch operations, test databases, and intermediate build directories.
Ideal Use Cases#
- DOKS (DigitalOcean Kubernetes) Heavy Worker Nodes: Serving as core compute nodes handling dozens of microservice pods, queue consumers, and background tasks.
- Enterprise CI/CD Build Hubs: Hosting self-managed GitLab Runner or GitHub Actions agents, compiling massive C++, Rust, or container-based projects concurrently.
- High-Concurrency Multiplayer Game Servers: Running low-latency game rooms, physics simulations, and state synchronization engines with zero core throttling.
- Parallel Media Transcoding Arrays: Managing multiple parallel FFmpeg processes converting raw video streams into multiple resolutions simultaneously.
Billing & Operational Efficiency#
- Per-Second Billing & 672-Hour Monthly Cap: Billed per second with a monthly billing cap at 672 hours (28 days). Running the server continuously beyond 672 hours in a month incurs no additional hourly charges.
- Power Off vs. Destroy: Because this instance locks down 32 dedicated physical hyper-threads and 400 GiB of local NVMe on the host, billing continues when powered off. For transient benchmark runs or batch processing, take a snapshot and destroy the instance when idle.
- Data Architecture & Backups: Use the 400 GiB NVMe disk for local scratch and OS operations. Store persistent databases on DigitalOcean Managed Databases or Volumes block storage, and enable automated backups (weekly adds 20%, daily adds 30%).
Final Recommendation#
For engineering teams requiring heavy 32-core parallel compute, 10 Gbps networking, and fast local NVMe storage, c-32-intel offers an enterprise-grade compute foundation.