
What to Do First During CPU Spikes: Distinguishing Bursts, Sustained Load, and Panel Limits#
When logging into your VPS and noticing a sudden CPU surge, avoid rushing into restarting the server or spending money on plan upgrades. Your first step should always be determining the exact nature of the workload: is it an intermittent burst occurring every few minutes, or a sustained queue caused by heavy application backlog?
According to the official Terms of Service, BandwagonHost separates short-term CPU bursts from the one-hour average CPU allowance on non-SLA plans, with specific limits determined by the full plan name. This means briefly reaching 100% CPU utilization does not inherently constitute a policy violation. Only when the one-hour average consumption consistently exceeds your plan quota will the underlying hypervisor throttle available CPU cycles. During throttling, your VPS remains running, and an alert appears in the KiwiVM control panel; once average utilization returns within permitted limits, CPU restrictions lift automatically. Official terms do not guarantee that limits will clear instantly or within a set number of minutes, nor should a single snapshot of full CPU utilization be treated as evidence of policy enforcement.
Simultaneously observe real-world application performance. If your websites and API responses remain fully responsive, pages load without timeout queues, and the KiwiVM dashboard displays no CPU warnings, brief spikes generally have minimal impact on visitor experience.
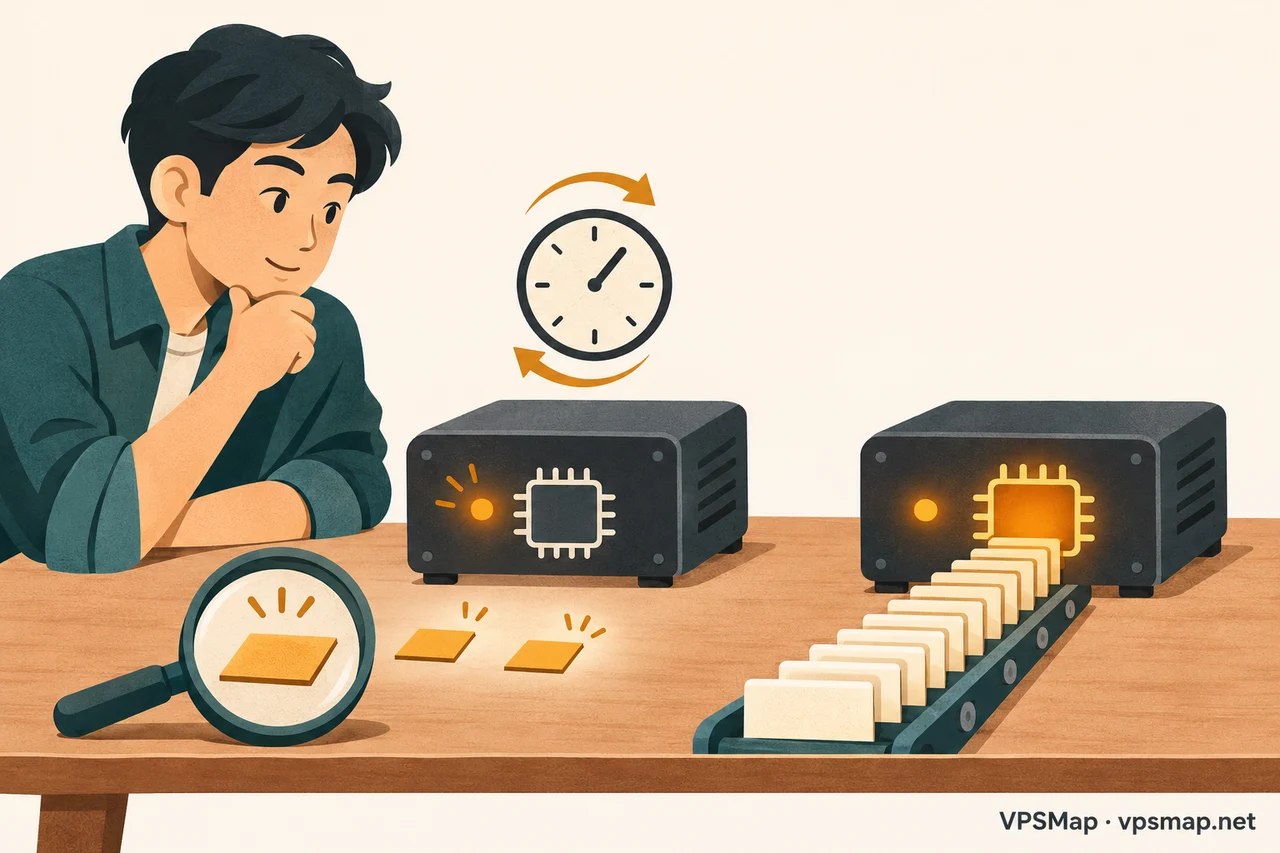
Understanding the contrast between these scenarios helps avoid unnecessary infrastructure spending:
- Brief Repeated Spikes: CPU briefly surges for several seconds at regular intervals before quickly falling back, leaving the system largely idle with normal traffic delivery.
- Sustained Overload Queues: CPU stays consistently elevated, average consumption over one hour breaches plan thresholds, panel warnings activate, and public requests experience delays.
Continuous Observation and Capturing PIDs with Read-Only Linux Tools#
Once investigation is deemed necessary, gather diagnostic data inside the operating system using safe, read-only tools without modifying any system configurations or running services.
Begin with a short observation window using top in batch mode:
top -b -d 2 -n 6This command captures 6 iterations at 2-second intervals, producing its first output immediately without an initial delay. This brief window allows you to monitor PID, COMMAND, %CPU, and execution rhythm. Keep in mind that short-lived or intermittent processes can appear and terminate between sampling intervals; failing to capture activity in one sample does not rule out its existence. This command applies to Linux environments equipped with procps; consult distribution package documentation if the tool is absent.
To capture a broad snapshot of the process table, use ps to review the first few lines of the sorted list:
ps -eo pid,ppid,comm,pcpu,pmem --sort=-pcpu | head -n 16Because head -n 16 includes the table header, it displays the top rows of the output. Note the exact reporting metric: %CPU (or pcpu) in ps represents the ratio of lifetime CPU time to total elapsed process runtime. It is neither a 2-second real-time instant sample nor the provider's one-hour billing metric. Sorting by pcpu orders processes by their lifetime average ratio rather than momentary real-time peaks. Using comm displays executable names without full command-line arguments, reducing exposure of sensitive tokens or credentials, though outputs must still be sanitized before sharing.
After identifying a candidate PID, inspect its runtime duration and parent process details using these two queries:
ps -p PID -o pid,ppid,comm,etimes,pcpu,pmemps -p PARENT_PID -o pid,ppid,commAlways replace the placeholders PID and PARENT_PID with actual observed numeric values. Ephemeral processes may terminate quickly, and Linux reuses PID values, so verify that the process is still running prior to inspection. An executable name alone does not prove software provenance, legitimacy, or whether it can safely be stopped; capturing runtime duration and parental lineage provides the foundation for accurate troubleshooting.
Correlating System Timers and Tracing Process Origins#
When process activity follows a strict repeating schedule, correlate the observed spike timestamps against system scheduling mechanisms.
On systems utilizing systemd, inspect timer units with the following command:
systemctl list-timers --all --no-pagerThis lists all timer units currently loaded into systemd memory (including inactive units), alongside their last trigger time, next scheduled run, and associated service. Compare these schedules against the timestamps of your CPU spikes. Note that this command only applies to systemd environments and does not reveal standard cron jobs, container-internal schedules, or application-level execution loops; the absence of matching timers does not guarantee no periodic background task exists. Furthermore, identical trigger times provide diagnostic clues rather than definitive proof of causality.
Regarding public case reports, user William Long posted on X on 2026-11-01 describing brief CPU spikes recurring every minute in a specific environment. This represents an isolated individual user report rather than an official confirmation from the provider, and should not be generalized to all operating setups.
Handle identified tasks based on their origin:
- User Application Workloads: If spikes stem from confirmed business tasks such as database exports, cache rebuilds, or log maintenance, optimize execution by adjusting concurrency, implementing worker queues, or shifting jobs to low-traffic maintenance windows.
- Unfamiliar System Components: If you encounter an unfamiliar process or preinstalled management daemon, never terminate processes or disable services based on unverified online recommendations, as this may break virtualization management channels. Instead, collect diagnostic logs and seek official guidance.
When to Optimize Existing Workloads vs. Considering Plan Upgrades#
Upgrading server tiers should never be used to mask unverified background processes. If an underlying software loop or misconfigured service causes spikes, moving to a larger plan will merely consume compute on a more expensive machine while leaving the problem unresolved.
Plan upgrades are warranted only when your verified, production workloads consistently exceed hardware allocations and the sustained one-hour CPU allowance. Different BandwagonHost plan tiers focus on distinct network transit options and datacenter regions; choosing a premium network tier does not resolve computational spikes.
Review the following verified plan details:
| Plan Name | Hardware Specifications | Port Speed and Transit Profile | Reference Full-Term Price | Verified Purchase Link |
|---|---|---|---|---|
| Basic 40G / 2GB (PID 45) | 3 vCPU / 2048 MB RAM / 40 GB Storage / 2000 GB Monthly Bandwidth | 1000 Mbps port speed, example datacenter USCA_2 | $99.99 annually (shortest cycle semiannual at $52.99) | Order Basic 40G Annually |
| E-Commerce 40G / 2GB (PID 88) | 3 vCPU / 2048 MB RAM / 40 GB Storage / 2000 GB Monthly Bandwidth | 2500 Mbps port speed, example datacenter USCA_9 | $299.99 annually (shortest cycle quarterly at $89.99) | Order E-Commerce 40G Annually |
When evaluating these options, recognize that E-Commerce pricing reflects specialized transit routes designed for targeted audience connectivity, rather than mitigation for anomalous processes. Port speeds represent virtual interface capabilities, not guaranteed continuous transit bandwidth. Annual billing options require upfront payment for the full term rather than monthly deductions. Available billing cycles and inventory reflect conditions observed on 2026-11-03 and depend on real-time checkout availability.
To explore additional active tiers and global terms, visit the BandwagonHost Main Portal or review the BandwagonHost Plan Catalog.
Preparing a Concise Diagnostic Record for Support Inquiry#
BandwagonHost operates self-managed KVM VPS hosting. The provider manages physical node health and network connectivity, while operating system maintenance, daemon configuration, and data backups remain the user's responsibility. Consequently, any inquiry directed to official support must provide clear, concise, and read-only facts.
If you suspect an unfamiliar process is tied to an operating system template, assemble a minimal diagnostic log before contacting support via Official Support Channels:
- Timestamp and Timezone: Note exact spike timestamps with explicit timezone notation (such as UTC or local offset).
- Production Impact: State whether user-facing web services or APIs experienced slowdowns or failed connections during the event.
- Spike Characteristics: Detail burst duration in seconds, recurrence frequency, and whether the KiwiVM dashboard indicated CPU throttling.
- Process Output Fields: Attach the PID, parent PID, executable name (comm), and runtime duration gathered via read-only commands.
- Environment Details: List the Linux distribution, kernel release, and datacenter location code.
Before submitting, perform a thorough privacy audit: remove all private keys, passwords, API tokens, full command lines containing secrets, customer records, and billing data. Focus the inquiry on clarifying the component's designated function, applicable template versions, and recommended maintenance procedures. Support teams do not commit to specific turnaround intervals or predefined resolutions.
For additional setup and control panel references, consult the BandwagonHost Overview and the KiwiVM API Guide.
Official Documentation and References:
- BandwagonHost Terms of Service
- BandwagonHost Product Catalog
- Linux top(1) Manual Page
- Linux ps(1) Manual Page
- systemd systemctl(1) Manual Page
Information verification date: 2026-11-03.