DigitalOcean c2-16vcpu-32gb-intel Droplet Review: Dedicated 16-Core Power with 400 GiB NVMe
Updated
The Significance of Local NVMe Capacity on 16-Core Machines#
When scaling multi-threaded compilation and batch workloads on high-core cloud servers, developers often hit a frustrating bottleneck: while 16 dedicated cores process data rapidly, a 200 GiB boot disk fills up quickly when hosting Docker layers, package caches, and unpacked build artifacts.
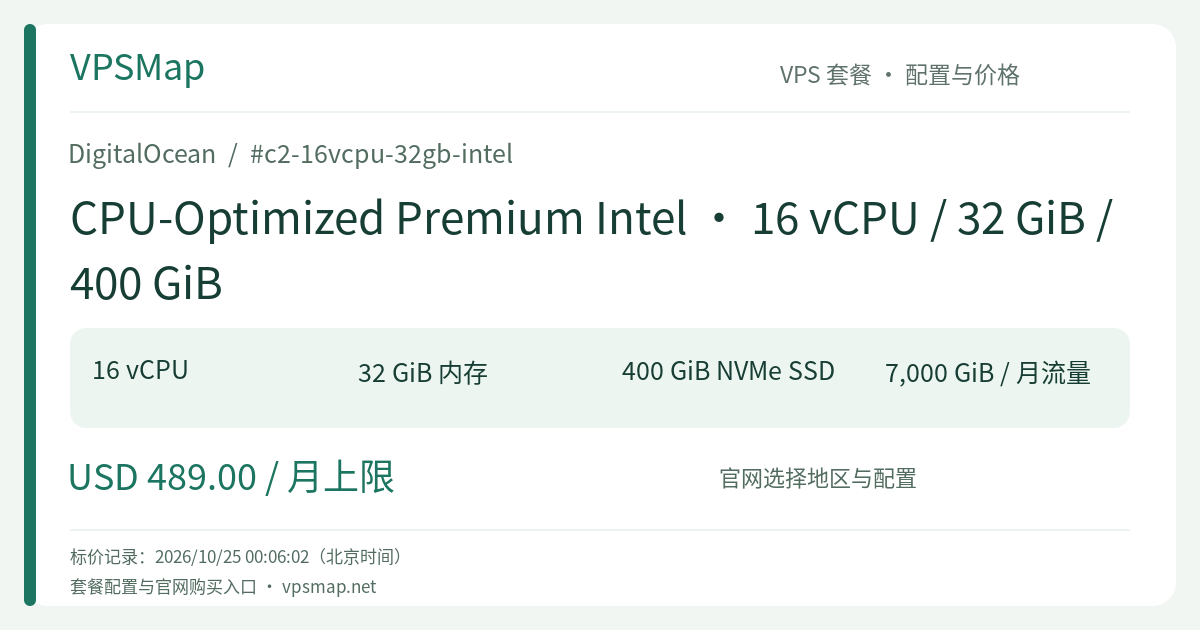
The DigitalOcean c2-16vcpu-32gb-intel solves this challenge directly. Part of the CPU-Optimized Premium Intel 2X Storage tier, it pairs 16 dedicated Intel Xeon cores and 32 GiB of RAM (2:1 ratio) with 400 GiB of local hypervisor-attached NVMe storage.
Architectural Advantages & Strengths#
1. Direct NVMe vs. Network Block Storage#
When disk space runs low, attaching network block storage (DigitalOcean Volumes) is a standard option. However, network-attached volumes carry network protocol latency and IOPS caps. When 16 threads perform concurrent, random reads and writes—such as compiling complex codebases with deep dependency trees or extracting archives—network storage can trigger high I/O wait times.
In contrast, the 400 GiB NVMe on c2-16vcpu-32gb-intel is attached directly to the physical PCIe bus of the hypervisor:
- Low Latency & High Parallel IOPS: All 16 threads can read and write without saturating the disk queue.
- Deeper Local Caching: Retain multiple Docker layer caches, compilation objects, and artifacts locally to shave minutes off repetitive pipeline runs.
2. 16 Dedicated Xeon Hyper-Threads#
Unlike shared-CPU Droplets, where virtual threads compete dynamically for CPU cycles, CPU-Optimized Droplets assign dedicated hyper-threads backed by 3rd Gen Intel Xeon Scalable processors (base clock > 2.6 GHz). Regardless of neighboring workloads on the host, your server retains 100% compute access without throttling.
3. 10 Gbps Network & 7,000 GiB Bandwidth Pool#
Premium Intel Droplets provide up to 10 Gbps of outbound throughput, exporting data up to 5x faster than standard regular-CPU Droplets. With 7,000 GiB of included monthly public transfer pooled across your team, ingress and egress bottlenecks are virtually non-existent for heavy microservice traffic or package publishing.
Ideal Workload Scenarios#
- Heavy CI/CD Runner Nodes: Self-hosted GitLab Runners, Jenkins agents, or GitHub Actions runners managing dozens of concurrent Docker-in-Docker builds.
- Media Encoding Pipelines: Ingesting high-definition raw footage, processing multi-pass transcodes, and packaging HLS segments locally before publishing to object storage.
- Staging & QA Databases: Hosting full-scale staging databases with hundreds of gigabytes of seed data, enabling realistic performance audits without production lag.
- Analytics Ingestion & Log Forwarders: Running vector search nodes or local ClickHouse/Elasticsearch instances requiring fast ingest buffers and immediate responsiveness.
Cost & Practical Considerations#
- Cost-Benefit Ratio: Upgrading from the 200 GiB baseline to the 400 GiB
c2-16vcpu-32gb-inteladds only$52/month ($0.077/hour). Gaining an extra 200 GiB of ultra-fast local NVMe without the operational complexity or latency of network volumes represents significant value for busy pipelines. - Power Off vs. Destroy: Dedicated hyper-threads and NVMe space remain reserved on the host machine while powered off. To stop charges completely during long idle phases, snapshot the instance and destroy it.
- Data Architecture: NVMe storage is tied to the Droplet lifecycle. Maintain durable backups using DigitalOcean’s native snapshot tools, automated backup services (20% weekly / 30% daily), or sync files to Spaces object storage.
Summary#
For teams demanding sustained 16-core compute paired with generous, lightning-fast local scratch disk space, c2-16vcpu-32gb-intel provides an exceptionally well-balanced production foundation.