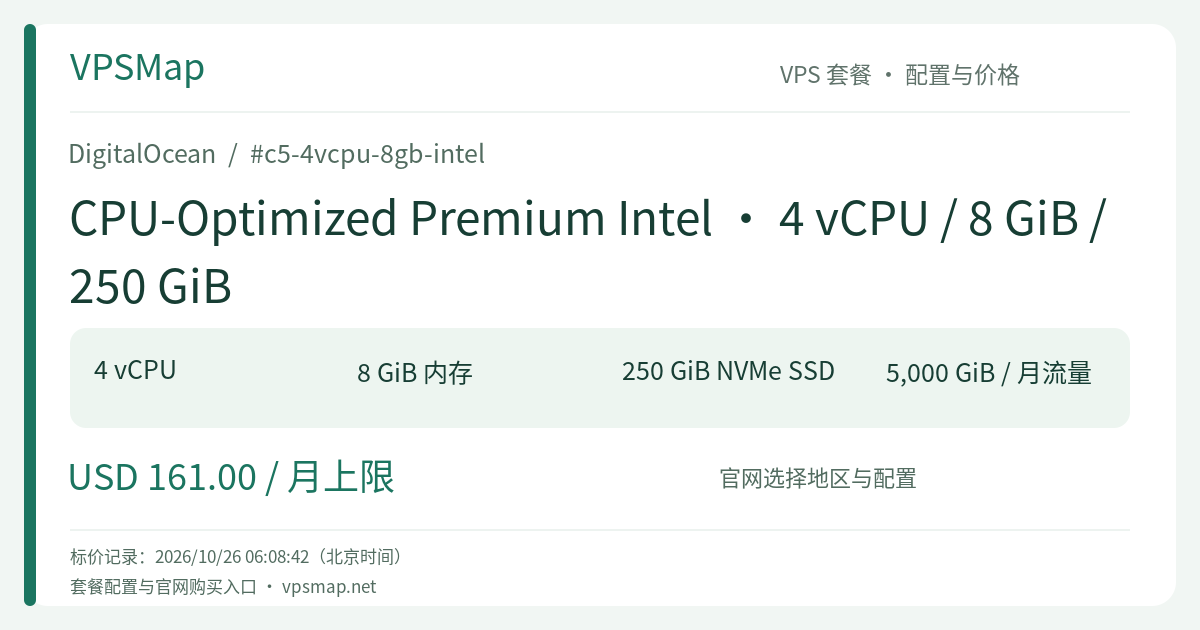
DigitalOcean c5-4vcpu-8gb-intel In-Depth: 250 GiB Local NVMe for Heavy I/O and Media Pipelines
Updated
When Compute Is No Longer Throttled by Disk I/O: The Power of 250 GiB Local NVMe#
In many intensive computing tasks, the real bottleneck isn't the raw speed of the processor—it's disk I/O failing to keep pace with the CPU.
Consider this real-world operational friction: when running high-bitrate media transcoding with FFmpeg, the CPU is primed to execute at 100% capacity. However, source video decompression and temporary chunking get bottlenecked by slow disk read/writes, leaving compute threads stuck in I/O Wait. Similarly, compiling massive codebases (such as AOSP, Chromium, or complex Rust mono-repos) generates hundreds of thousands of intermediate object files; a small or slow disk quickly fills up or saturates storage queues.
The c5-4vcpu-8gb-intel Droplet is purpose-engineered to bridge the gap between dedicated compute and high-capacity, low-latency storage. While delivering 4 dedicated Intel Ice Lake vCPUs and 8 GiB of RAM, it increases the host-attached NVMe storage to a massive 250 GiB—five times the baseline capacity. This enables you to stage raw media assets, build caches, and datasets directly on ultra-fast local silicon, ensuring all 4 dedicated cores run at full throttle.
Direct-Attached NVMe vs. Network Volumes: Latency vs. Throughput#
When designing a high-throughput pipeline, storage topology dictates your performance ceiling:
- Option A (Baseline Droplet + Attached Block Storage Volume): While network-attached volumes are great for elastic archival storage, every read and write must be serialized into network packets traversing a virtualized fabric. Under intense random I/O from dozens of parallel compilation or encoding threads, microsecond-level latency spikes accumulate, causing valuable CPU cycles to idle.
- Option B (c5-4vcpu-8gb-intel with Native 250 GiB NVMe): The entire 250 GiB resides directly on the host's PCIe bus. The resulting multi-gigabyte-per-second parallel throughput and sub-millisecond latencies eliminate storage bottlenecks entirely. Temporary files, scratchpads, and intermediate artifacts are processed at bare-metal speeds.
Dedicated 4-Core Ice Lake Muscle Meets 10 Gbps Pipe#
Every metric on this machine is dialed in for demanding batch operations:
- 4 Dedicated 3rd Gen Intel Xeon Scalable (Ice Lake) Threads: Clocked at a stable base frequency above 2.6 GHz with advanced vector instruction support (AVX-512). Complex math, media encoding, and data serialization execute with deterministic speed and zero host competition.
- Up to 10 Gbps Network Pipe: Premium Intel Droplets feature up to 10 Gbps bandwidth. Ingesting raw assets from Spaces object storage or pushing completed packages to external targets saturates network interfaces without delay.
- 5,000 GiB Monthly Team Transfer Allowance: A generous outbound allowance pooled at the team level, with completely free inbound traffic and free VPC transfers.
Primary Workload Profiles#
- Media Transcoding and Streaming Packaging Farms: Downloading high-bitrate video masters, decoding, transcoding into multi-bitrate H.264/H.265/AV1 streams, and generating HLS/DASH chunk directories. A 250 GiB direct NVMe drive provides the capacity to store dozens of raw video masters and frame caches simultaneously.
- Large-Scale Continuous Integration (C++ / Rust / Android Pipelines): Storing substantial compilation caches (ccache, sccache) and multi-version dependency tarballs. With 250 GiB on-disk, clean builds become incremental, slashing turnaround times for development teams.
- ETL Pipelines, Log Aggregation, and Data Preprocessing: Staging uncompressed raw event streams, executing parsing, deduplication, and transformation before streaming into managed databases or data warehouses.
Cost Optimization: Maximizing Efficiency with Per-Second Billing#
This configuration offers high flexibility for bursty or scheduled workloads:
- On-Demand Spin-Up with Per-Second Precision: Billed per second with a 60-second minimum ($0.01). If your business requires a nightly 3-hour batch run, spin up a c5-4vcpu-8gb-intel instance via API or
doctl, execute the jobs, upload the results to Spaces, and destroy the instance. You pay only for the exact runtime. - Predictable Cap for Persistent Operations: For long-running CI runners or continuous workers, monthly billing caps at 672 hours (28 days), making long months predictable and affordable.
Sizing Verdict & Purchase Link#
If your technical stack demands sustained 4-core dedicated CPU power paired with an expansive, ultra-fast local scratchpad that will never bottleneck compute operations, the c5-4vcpu-8gb-intel is an uncompromising, high-performance solution.
Regional capacity is verified inside the console upon deployment. Launch your Droplet directly through the link below: